Siglip2 Large Patch16 512 Ind 32768
This model is a 25.91% smaller version of google/siglip2-large-patch16-512 optimized for Indonesian language via vocabulary size reduction using the trimming method. This trimmed model should perform similarly to the...
Model source
- Kind
- Text model
- File size
- 2.44 GB
- Base model
- google/siglip2-large-patch16-512
- Version
- vmodel
- Updated
- Oct 22, 2026
- Downloads
- 4
- Source
- Hugging Face
Source description
siglip2-large-patch16-512-ind-32768
This model is a 25.91% smaller version of google/siglip2-large-patch16-512 optimized for Indonesian language via vocabulary size reduction using the trimming method.
This trimmed model should perform similarly to the original model with only 32,768 tokens and a much smaller memory footprint. However, it may not perform well for other languages as tokens not commonly used in the selected languages were removed from the vocabulary.
Model Statistics
| Metric | Original | Trimmed | Reduction |
|---|---|---|---|
| Vocabulary size | 256,000 tokens | 32,768 tokens | 87.20% |
| Model size | 882,313,218 params | 653,723,650 params | 25.91% |
image
Mining Dataset Statistics
- Number of texts used for mining: 200,000 texts
- Dataset: lbourdois/fineweb-2-trimming
Usage
Transformers (zero-shot image classification)
from transformers import pipeline

# load pipeline
image_classifier = pipeline(model="alphaedge-ai/siglip2-large-patch16-512-ind-32768", task="zero-shot-image-classification")

# load image and candidate labels
image = "http://images.cocodataset.org/val2017/000000039769.jpg"
candidate_labels = ["Potential label 1 in Indonesian", "Potential label 2 in Indonesian", "Potential label 3 in Indonesian", "Potential label 4 in Indonesian"]

# run inference
outputs = image_classifier(image, candidate_labels)
print(outputs)
Sentence-transformers (texts-images similarity)
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("alphaedge-ai/siglip2-large-patch16-512-ind-32768")

images = [
    "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg",
    "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
    "https://huggingface.co/datasets/huggingface/cats-image/resolve/main/cats_image.jpeg"
]
texts = ["Text 1 in Indonesian", "Text 2 in Indonesian", "Text 3 in Indonesian", "Text 4 in Indonesian"]

image_embeddings = model.encode(images)
text_embeddings = model.encode(texts)
print(image_embeddings.shape, text_embeddings.shape)

similarities = model.similarity(image_embeddings, text_embeddings)
print(similarities)
Citations
SigLIP 2
@misc{tschannen2025siglip2multilingualvisionlanguage,
      title={SigLIP 2: Multilingual Vision-Language Encoders with Improved Semantic Understanding, Localization, and Dense Features},
      author={Michael Tschannen and Alexey Gritsenko and Xiao Wang and Muhammad Ferjad Naeem and Ibrahim Alabdulmohsin and Nikhil Parthasarathy and Talfan Evans and Lucas Beyer and Ye Xia and Basil Mustafa and Olivier Hénaff and Jeremiah Harmsen and Andreas Steiner and Xiaohua Zhai},
      year={2025},
      eprint={2502.14786},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2502.14786},
}
Trimming blog post
@misc{hf_blogpost_trimming,
      title={Introduction to Trimming},
      author={Loïck BOURDOIS and Tom AARSEN and Bram VANROY and Christopher AKIKI and Woojun JUNG and Manuel ROMERO and Prithiv SAKTHI},
      year={2026},
      url={https://huggingface.co/blog/lbourdois/introduction-to-trimming},
}
Sources
1 source
Sources
1 sourceVerified Oct 22
Model artifacts
1 artifact
Model artifacts
1 artifactSource excerpts
3 excerpts
Source excerpts
3 excerpts--- pipeline_tag: zero-shot-image-classification language: ind license: apache-2.0 tags: - trimmed library_name: sentence-transformers base_model: google/siglip2-large-patch16-512 base_model_relation: quantized datasets: - lbourdois/fineweb-2-trimming --- # siglip2-large-patch16-512-ind-32768 This model is a **25.91%** smaller version of [google/siglip2-large-patch16-512](https://huggingface.co/google/siglip2-large-patch16-512) optimized for **Indonesian** language via vocabulary size reduction using the [trimming](https://huggingface.co/blog/lbourdois/introduction-to-trimming) method. This trimmed model should perform similarly to the original model with only 32,768 tokens and a much smaller memory footprint. However, it may not perform well for other languages as tokens not commonly used in the selected languages were removed from the vocabulary. ## Model Statistics | Metric | Original | Trimmed | Reduction | |--------|----------|---------|-----------| | **Vocabulary size** | 256,000 tokens | 32,768 tokens | **87.20%** | | **Model size** | 882,313,218 params | 653,723,650 params | **25.91%** | 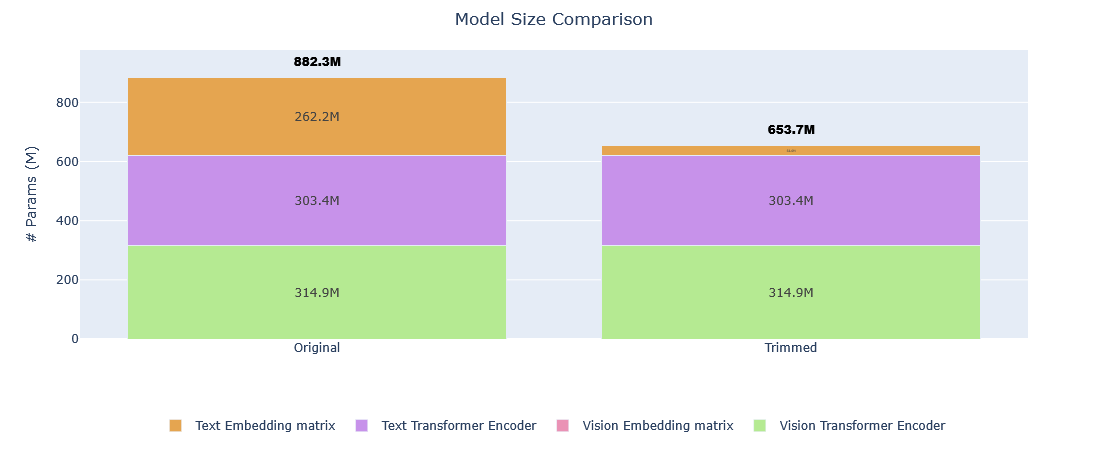 ## Mining Dataset Statistics - **Number of texts used for mining**: 200,000 texts - **Dataset**: [lbourdois/fineweb-2-trimming](https://huggingface.co/datasets/lbourdois/fineweb-2-trimming) ## Usage #### Transformers (zero-shot image classification) ```python from transformers import pipeline # load pipeline image_classifier = pipeline(model="alphaedge-ai/siglip2-large-patch16-512-ind-32768", task="zero-shot-image-classification") # load image and candidate labels image = "http://images.cocodataset.org/val2017/000000039769.jpg" candidate_labels = ["Potential label 1 in Indonesian", "Potential label 2 in Indonesian", "Potential label 3 in Indonesian", "Potential label 4 in Indonesian"] # run inference outputs = image_classifier(image, candidate_labels) print(outputs) ``` #### Sentence-transformers (texts-images similarity) ```python from sentence_transformers import SentenceTransformer model = SentenceTransformer("alphaedge-ai/siglip2-large-patch16-512-ind-32768") images = [ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg", "https://huggingface.co/datasets/hu...
Source context: 4 downloads · 0 likes · Pipeline zero-shot-image-classification · Library sentence-transformers · Repo alphaedge-ai/siglip2-large-patch16-512-ind-32768
Source context: 25 downloads · 0 likes · Pipeline zero-shot-image-classification · Library sentence-transformers · Repo alphaedge-ai/siglip2-large-patch16-512-ind-32768
