M2 Encoder 1B
M2-Encoder-1B is a Hugging Face export of the bilingual vision-language foundation model from the paper M2-Encoder: Advancing Bilingual Image-Text Understanding by Large-scale Efficient Pretraining.
Fonte do modelo
- Tipo
- Other
- Tamanho do arquivo
- 1,14–2,72 GB
- Versão
- vRevision dcdf562
- Atualizado
- 28 de set. de 2026
- Downloads
- 12
- Fonte
- Hugging Face
Descrição da fonte
M2-Encoder-1B
M2-Encoder-1B is a Hugging Face export of the bilingual vision-language foundation model from the paper M2-Encoder: Advancing Bilingual Image-Text Understanding by Large-scale Efficient Pretraining.
It supports Chinese-English image-text retrieval, zero-shot image classification, transformers remote-code loading, ONNXRuntime inference, and Hugging Face Inference Endpoints via the bundled handler.py.
This is the larger M2-Encoder variant with a wider backbone and 1024-dimensional embeddings, intended for better retrieval and zero-shot classification quality.
Benchmark overview
Links
- Paper: https://arxiv.org/abs/2401.15896
- Official code: https://github.com/alipay/Ant-Multi-Modal-Framework/tree/main/prj/M2_Encoder
- ModelScope source model:
M2Cognition/M2_Encoder_Large - Hugging Face repo:
malusama/M2-Encoder-1B
At A Glance
| Item | Value |
|---|---|
| Variant | M2-Encoder-1B |
| Languages | Chinese, English |
| Embedding dimension | 1024 |
| Image size | 224 |
| Main tasks | Image-text retrieval, zero-shot image classification, bilingual feature extraction |
| Weight format | safetensors |
| ONNX export | onnx/text_encoder.onnx, onnx/image_encoder.onnx |
Files In This Repo
m2_encoder_1B.safetensors: maintransformersweight fileonnx/text_encoder.onnx: text embedding encoderonnx/image_encoder.onnx: image embedding encoderexamples/run_onnx_inference.py: runnable ONNX examplehandler.py: custom handler for Hugging Face Inference Endpoints
Transformers Usage
ModelScope-equivalent scoring
The original ModelScope sample computes probabilities from raw normalized embedding dot products:
from transformers import AutoModel, AutoProcessor

repo_id = "malusama/M2-Encoder-1B"

model = AutoModel.from_pretrained(repo_id, trust_remote_code=True)
processor = AutoProcessor.from_pretrained(repo_id, trust_remote_code=True)

text_inputs = processor(
    text=["杰尼龟", "妙蛙种子", "小火龙", "皮卡丘"],
    return_tensors="pt",
)
image_inputs = processor(images="pokemon.jpeg", return_tensors="pt")

text_outputs = model(**text_inputs)
image_outputs = model(**image_inputs)

probs = (image_outputs.image_embeds @ text_outputs.text_embeds.t()).softmax(dim=-1)
print(probs)
CLIP-style logits
model(**inputs) also returns logits_per_image and logits_per_text, which use the model's learned logit_scale.
Those logits are useful, but they are not the same computation as the raw dot product used in the original ModelScope demo.
ONNXRuntime Usage
This repo also includes two ONNX exports:
onnx/text_encoder.onnxonnx/image_encoder.onnx
Minimal example:
import importlib
import json
import os
import sys

import onnxruntime as ort
from huggingface_hub import snapshot_download
from PIL import Image

repo_id = "malusama/M2-Encoder-1B"
model_dir = snapshot_download(repo_id=repo_id)
sys.path.insert(0, model_dir)

tokenizer_config = json.load(open(os.path.join(model_dir, "tokenizer_config.json"), "r", encoding="utf-8"))
GLMChineseTokenizer = importlib.import_module("tokenization_glm").GLMChineseTokenizer
M2EncoderImageProcessor = importlib.import_module("image_processing_m2_encoder").M2EncoderImageProcessor

tokenizer = GLMChineseTokenizer(
    vocab_file=os.path.join(model_dir, "sp.model"),
    eos_token=tokenizer_config.get("eos_token"),
    pad_token=tokenizer_config.get("pad_token"),
    cls_token=tokenizer_config.get("cls_token"),
    mask_token=tokenizer_config.get("mask_token"),
    unk_token=tokenizer_config.get("unk_token"),
)
image_processor = M2EncoderImageProcessor.from_pretrained(model_dir)

text_inputs = tokenizer(
    ["杰尼龟", "妙蛙种子", "小火龙", "皮卡丘"],
    padding="max_length",
    truncation=True,
    max_length=52,
    return_special_tokens_mask=True,
    return_tensors="np",
)
image_inputs = image_processor(Image.open("pokemon.jpeg").convert("RGB"), return_tensors="np")

text_session = ort.InferenceSession(
    os.path.join(model_dir, "onnx", "text_encoder.onnx"),
    providers=["CPUExecutionProvider"],
)
image_session = ort.InferenceSession(
    os.path.join(model_dir, "onnx", "image_encoder.onnx"),
    providers=["CPUExecutionProvider"],
)

text_embeds = text_session.run(
    None,
    {
        "input_ids": text_inputs["input_ids"],
        "attention_mask": text_inputs["attention_mask"],
    },
)[0]
image_embeds = image_session.run(
    None,
    {"pixel_values": image_inputs["pixel_values"]},
)[0]
Runnable script:
python examples/run_onnx_inference.py --image pokemon.jpeg --text 杰尼龟 妙蛙种子 小火龙 皮卡丘
Inference Endpoints
This repo includes a handler.py for Hugging Face Inference Endpoints custom deployments.
Example request body:
{
  "inputs": {
    "text": ["杰尼龟", "妙蛙种子", "小火龙", "皮卡丘"],
    "image": "https://clip-cn-beijing.oss-cn-beijing.aliyuncs.com/pokemon.jpeg"
  },
  "parameters": {
    "return_probs": true,
    "return_logits": false
  }
}
Example response fields:
text_embeddingimage_embeddingscoresprobslogits_per_imagewhenreturn_logits=true
Evaluation Summary
According to the official project README and paper, the M2-Encoder series is trained on the bilingual BM-6B corpus and evaluated on:
- ImageNet
- ImageNet-CN
- Flickr30K
- Flickr30K-CN
- COCO-CN
The official project reports that the M2-Encoder family sets strong bilingual retrieval and zero-shot classification results, and that the 10B variant reaches 88.5 top-1 on ImageNet and 80.7 top-1 on ImageNet-CN in the zero-shot setting. See the paper for exact cross-variant comparisons.
The structured model-index metadata in this card is taken from the official paper tables for this released variant. On the Hugging Face page, those results should surface in the evaluation panel once the metadata is parsed.
Benchmark overview
Notes
- This is a Hugging Face remote-code adapter, not a native
transformersimplementation merged upstream. trust_remote_code=Trueis required forAutoModelandAutoProcessor.- This repo is intended for retrieval, classification, and embedding use cases, not text generation.
- The Hub export has been numerically checked against the official implementation for the published demo workflow.
Citation
@misc{guo2024m2encoder,
  title={M2-Encoder: Advancing Bilingual Image-Text Understanding by Large-scale Efficient Pretraining},
  author={Qingpei Guo and Furong Xu and Hanxiao Zhang and Wang Ren and Ziping Ma and Lin Ju and Jian Wang and Jingdong Chen and Ming Yang},
  year={2024},
  url={https://arxiv.org/abs/2401.15896}
}
Fontes
1 fonte
Fontes
1 fonteVerificado 28 de set.
Artefatos de modelo
3 artefatos
Artefatos de modelo
3 artefatosTrechos de fonte
2 trechos
Trechos de fonte
2 trechos--- license: apache-2.0 library_name: transformers pipeline_tag: zero-shot-image-classification language: - zh - en datasets: - BM-6B - ImageNet - ImageNet-CN - Flickr30K - Flickr30K-CN - COCO-CN tags: - onnx - feature-extraction - multimodal - image-text-retrieval - zero-shot-image-classification - bilingual - chinese - english - vision-language - custom-code model-index: - name: M2-Encoder-1B results: - task: type: zero-shot-image-classification name: Zero-Shot Image Classification dataset: name: ImageNet type: ImageNet metrics: - type: accuracy value: 85.4 name: Top-1 Accuracy - task: type: zero-shot-image-classification name: Zero-Shot Image Classification dataset: name: ImageNet-CN type: ImageNet-CN metrics: - type: accuracy value: 78.5 name: Top-1 Accuracy - task: type: image-text-retrieval name: Zero-Shot Image-Text Retrieval dataset: name: Flickr30K type: Flickr30K metrics: - type: mean_recall value: 95.4 name: MR - task: type: image-text-retrieval name: Zero-Shot Image-Text Retrieval dataset: name: COCO type: COCO metrics: - type: mean_recall value: 76.9 name: MR - task: type: image-text-retrieval name: Zero-Shot Image-Text Retrieval dataset: name: Flickr30K-CN type: Flickr30K-CN metrics: - type: mean_recall value: 93.6 name: MR - task: type: image-text-retrieval name: Zero-Shot Image-Text Retrieval dataset: name: COCO-CN type: COCO-CN metrics: - type: mean_recall value: 89.3 name: MR --- # M2-Encoder-1B `M2-Encoder-1B` is a Hugging Face export of the bilingual vision-language foundation model from the paper [M2-Encoder: Advancing Bilingual Image-Text Understanding by Large-scale Efficient Pretraining](https://arxiv.org/abs/2401.15896). It supports Chinese-English image-text retrieval, zero-shot image classification, `transformers` remote-code loading, ONNXRuntime inference, and Hugging Face Inference Endpoints via the bundled `handler.py`. This is the larger M2-Encoder variant with a wider backbone and 1024-dimensional embeddings, intended for better retrieval and zero-shot classification quality. 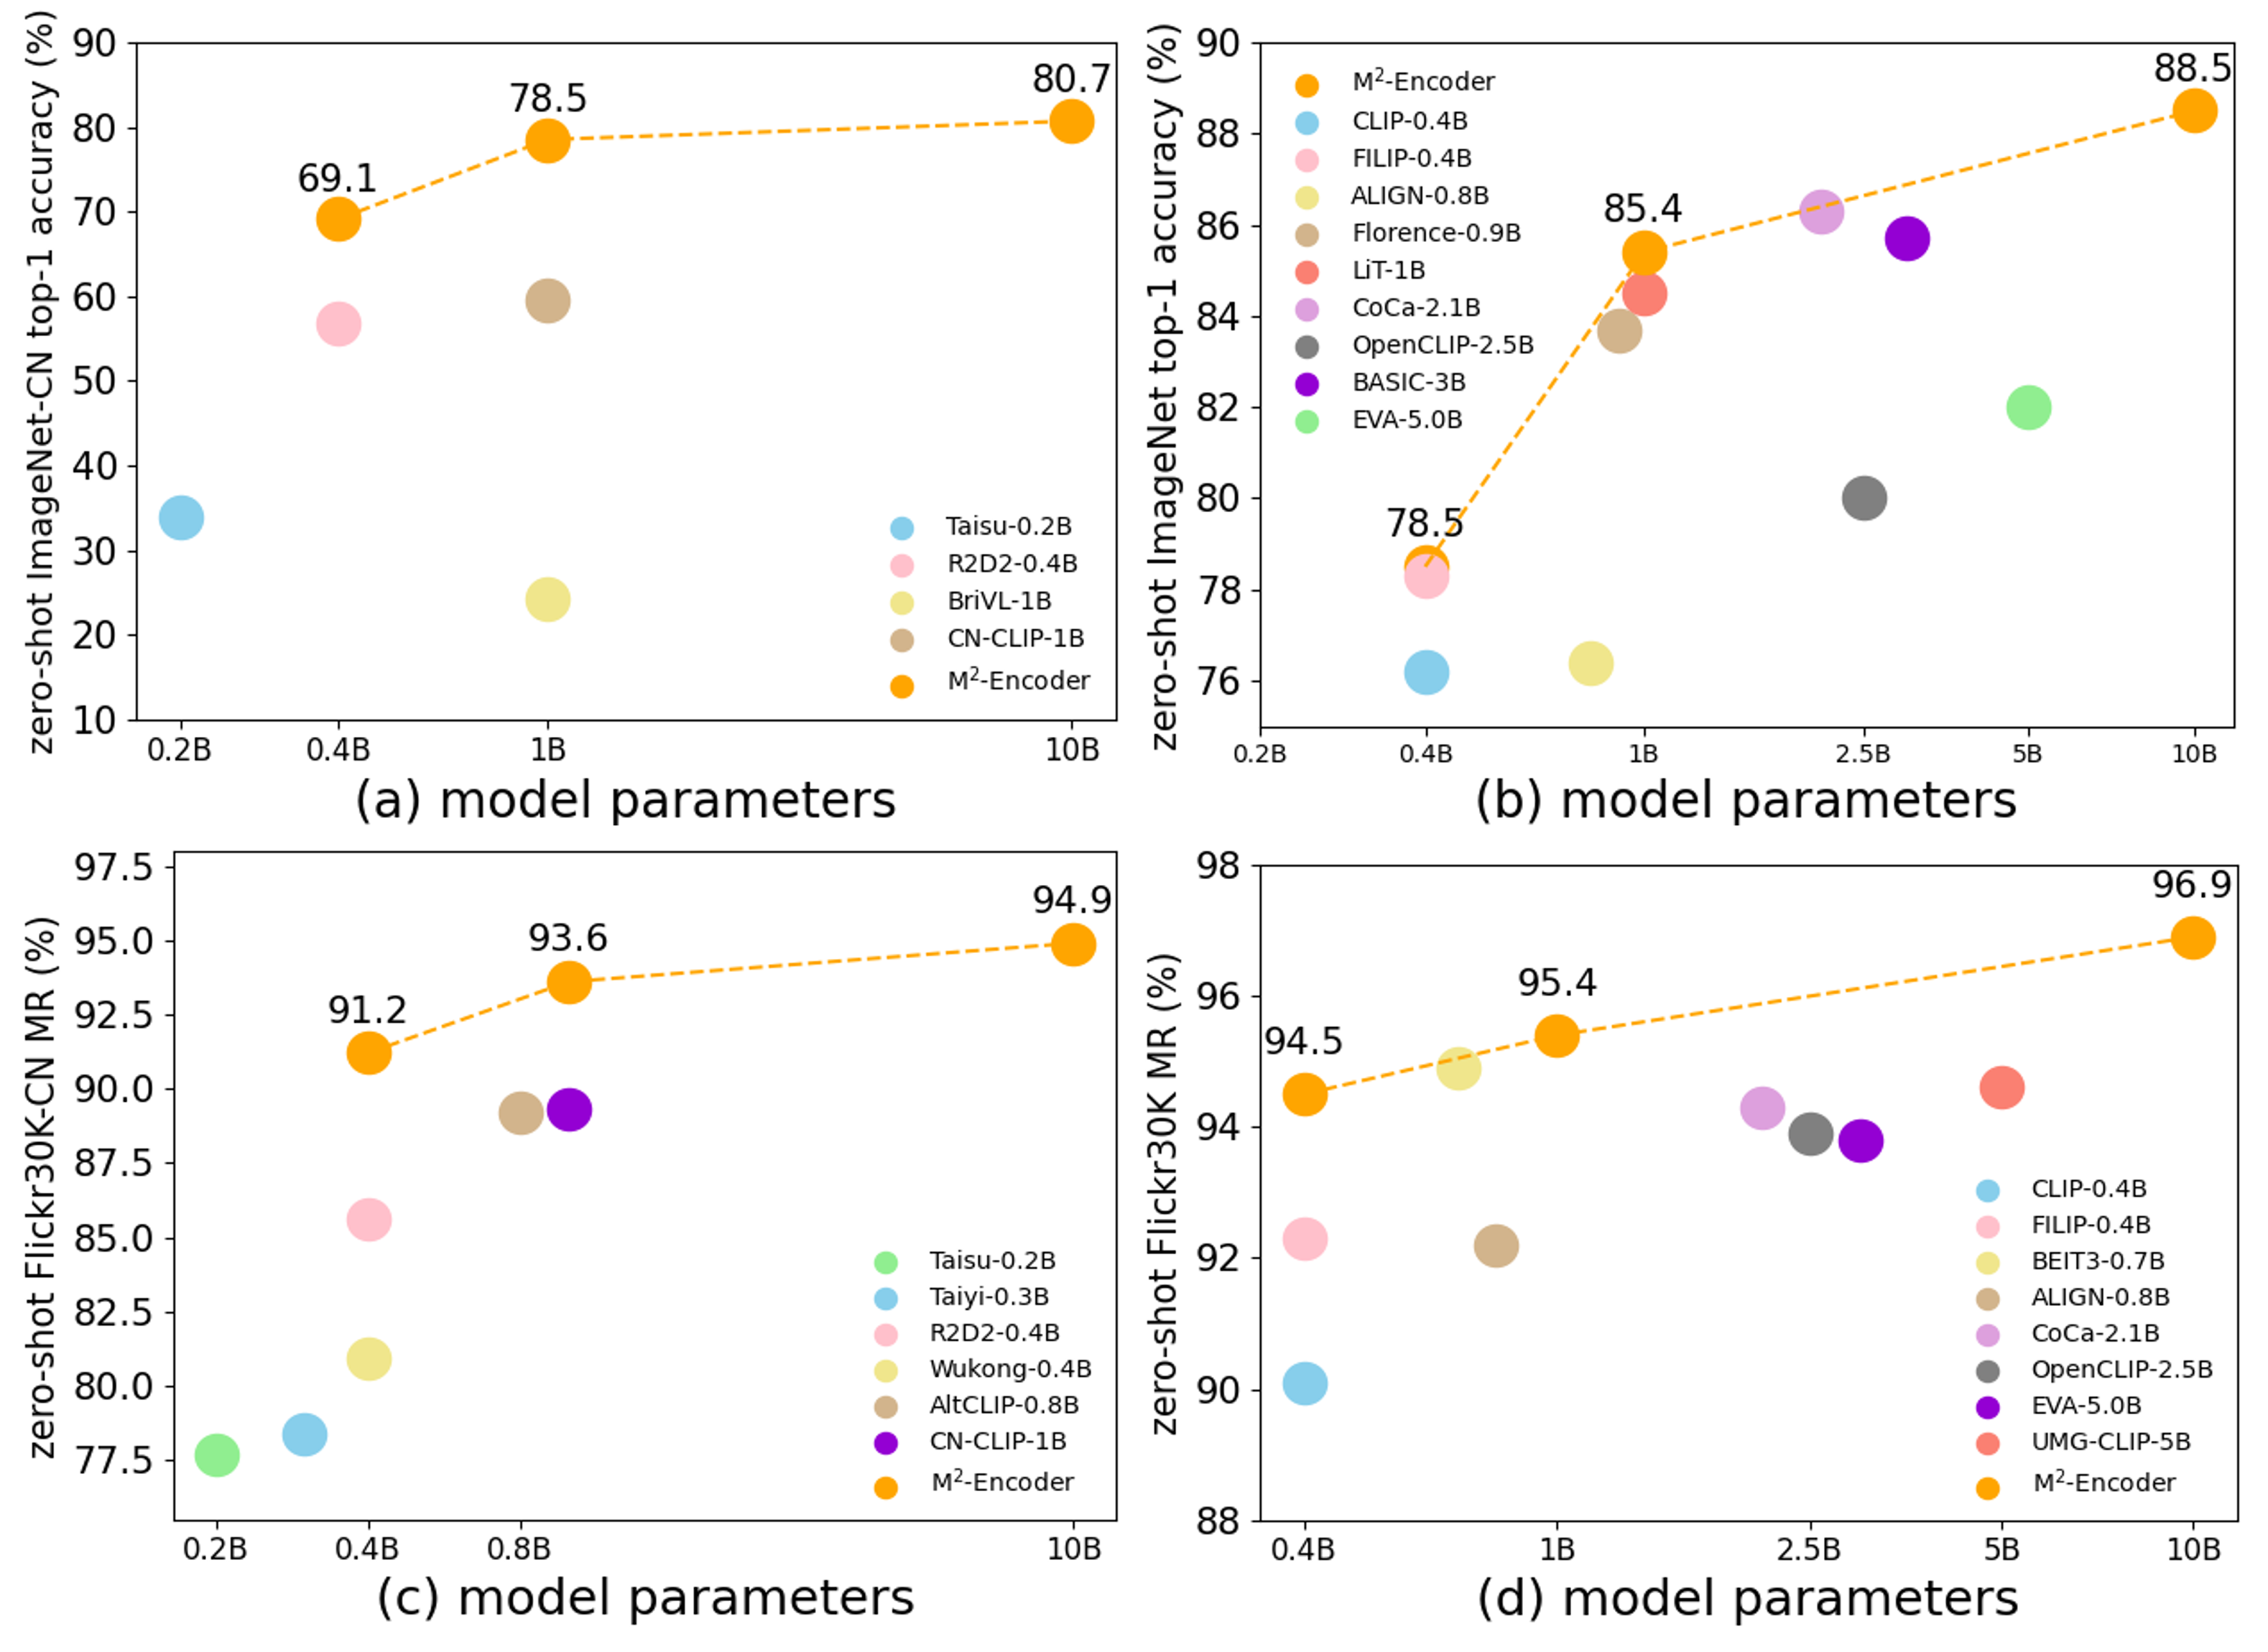 ## Links - Paper: https://arxiv.org/abs/2401.15896 - Official code: https://github.com/alipay/Ant-Multi-Modal-Framework/tree/main/prj/M2_Encoder - ModelScope so...
Source context: 12 downloads · 0 likes · Pipeline zero-shot-image-classification · Library transformers · Repo malusama/M2-Encoder-1B
