Siglip2 Giant Opt Patch16 384 Kat 16384
This model is a 14.75% smaller version of google/siglip2-giant-opt-patch16-384 optimized for Georgian language via vocabulary size reduction using the trimming method. This trimmed model should perform similarly to...
Source du modèle
- Type
- Other
- Taille du fichier
- 1,30–4,64 GB
- Modèle de base
- google/siglip2-giant-opt-patch16-384
- Version
- vRevision fb30207
- Mis à jour
- 22 sept. 2026
- Téléchargements
- 7
- Source
- Hugging Face
Description de la source
siglip2-giant-opt-patch16-384-kat-16384
This model is a 14.75% smaller version of google/siglip2-giant-opt-patch16-384 optimized for Georgian language via vocabulary size reduction using the trimming method.
This trimmed model should perform similarly to the original model with only 16,384 tokens and a much smaller memory footprint. However, it may not perform well for other languages as tokens not commonly used in the selected languages were removed from the vocabulary.
Model Statistics
| Metric | Original | Trimmed | Reduction |
|---|---|---|---|
| Vocabulary size | 256,000 tokens | 16,384 tokens | 93.60% |
| Model size | 1,871,885,426 params | 1,595,847,794 params | 14.75% |
image
Mining Dataset Statistics
- Number of texts used for mining: 200,000 texts
- Dataset: lbourdois/fineweb-2-trimming
Usage
Transformers (zero-shot image classification)
from transformers import pipeline

# load pipeline
image_classifier = pipeline(model="alphaedge-ai/siglip2-giant-opt-patch16-384-kat-16384", task="zero-shot-image-classification")

# load image and candidate labels
image = "http://images.cocodataset.org/val2017/000000039769.jpg"
candidate_labels = ["Potential label 1 in Georgian", "Potential label 2 in Georgian", "Potential label 3 in Georgian", "Potential label 4 in Georgian"]

# run inference
outputs = image_classifier(image, candidate_labels)
print(outputs)
Sentence-transformers (texts-images similarity)
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("alphaedge-ai/siglip2-giant-opt-patch16-384-kat-16384")

images = [
    "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg",
    "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
    "https://huggingface.co/datasets/huggingface/cats-image/resolve/main/cats_image.jpeg"
]
texts = ["Text 1 in Georgian", "Text 2 in Georgian", "Text 3 in Georgian", "Text 4 in Georgian"]

image_embeddings = model.encode(images)
text_embeddings = model.encode(texts)
print(image_embeddings.shape, text_embeddings.shape)

similarities = model.similarity(image_embeddings, text_embeddings)
print(similarities)
Citations
SigLIP 2
@misc{tschannen2025siglip2multilingualvisionlanguage,
      title={SigLIP 2: Multilingual Vision-Language Encoders with Improved Semantic Understanding, Localization, and Dense Features},
      author={Michael Tschannen and Alexey Gritsenko and Xiao Wang and Muhammad Ferjad Naeem and Ibrahim Alabdulmohsin and Nikhil Parthasarathy and Talfan Evans and Lucas Beyer and Ye Xia and Basil Mustafa and Olivier Hénaff and Jeremiah Harmsen and Andreas Steiner and Xiaohua Zhai},
      year={2025},
      eprint={2502.14786},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2502.14786},
}
Trimming blog post
@misc{hf_blogpost_trimming,
      title={Introduction to Trimming},
      author={Loïck BOURDOIS and Tom AARSEN and Bram VANROY and Christopher AKIKI and Woojun JUNG and Manuel ROMERO and Prithiv SAKTHI},
      year={2026},
      url={https://huggingface.co/blog/lbourdois/introduction-to-trimming},
}
Sources
1 source
Sources
1 sourceVérifié 10 sept.
Artefacts du modèle
2 artefacts
Artefacts du modèle
2 artefactsmodel-00001-of-00002.safetensors
safetensors · 4,64 GB · SHA-256 9b076632a356…df28 · Hugging Face
Téléchargermodel-00002-of-00002.safetensors
safetensors · 1,30 GB · SHA-256 24a9677f6eed…6182 · Hugging Face
TéléchargerExtraits de sources
2 extraits
Extraits de sources
2 extraits--- pipeline_tag: zero-shot-image-classification language: kat license: apache-2.0 tags: - trimmed library_name: sentence-transformers base_model: google/siglip2-giant-opt-patch16-384 base_model_relation: quantized datasets: - lbourdois/fineweb-2-trimming --- # siglip2-giant-opt-patch16-384-kat-16384 This model is a **14.75%** smaller version of [google/siglip2-giant-opt-patch16-384](https://huggingface.co/google/siglip2-giant-opt-patch16-384) optimized for **Georgian** language via vocabulary size reduction using the [trimming](https://huggingface.co/blog/lbourdois/introduction-to-trimming) method. This trimmed model should perform similarly to the original model with only 16,384 tokens and a much smaller memory footprint. However, it may not perform well for other languages as tokens not commonly used in the selected languages were removed from the vocabulary. ## Model Statistics | Metric | Original | Trimmed | Reduction | |--------|----------|---------|-----------| | **Vocabulary size** | 256,000 tokens | 16,384 tokens | **93.60%** | | **Model size** | 1,871,885,426 params | 1,595,847,794 params | **14.75%** | 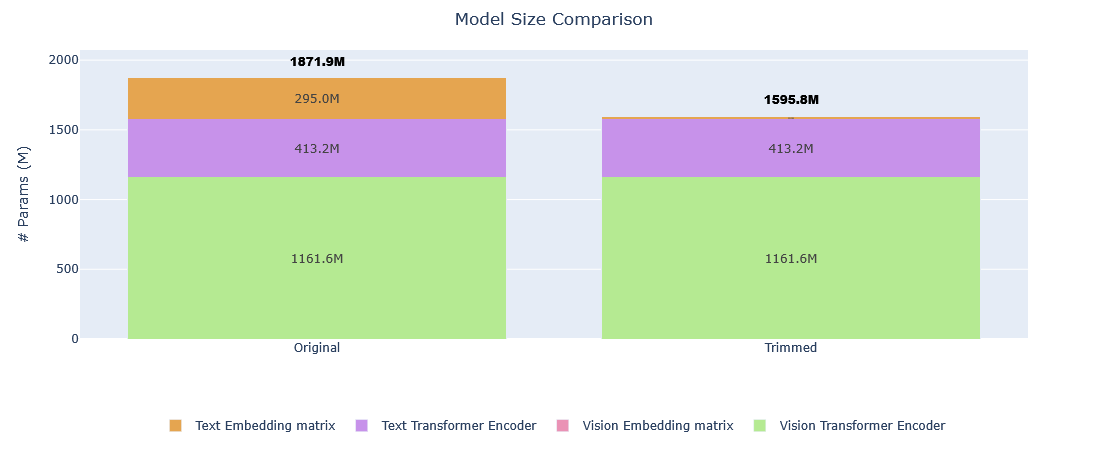 ## Mining Dataset Statistics - **Number of texts used for mining**: 200,000 texts - **Dataset**: [lbourdois/fineweb-2-trimming](https://huggingface.co/datasets/lbourdois/fineweb-2-trimming) ## Usage #### Transformers (zero-shot image classification) ```python from transformers import pipeline # load pipeline image_classifier = pipeline(model="alphaedge-ai/siglip2-giant-opt-patch16-384-kat-16384", task="zero-shot-image-classification") # load image and candidate labels image = "http://images.cocodataset.org/val2017/000000039769.jpg" candidate_labels = ["Potential label 1 in Georgian", "Potential label 2 in Georgian", "Potential label 3 in Georgian", "Potential label 4 in Georgian"] # run inference outputs = image_classifier(image, candidate_labels) print(outputs) ``` #### Sentence-transformers (texts-images similarity) ```python from sentence_transformers import SentenceTransformer model = SentenceTransformer("alphaedge-ai/siglip2-giant-opt-patch16-384-kat-16384") images = [ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg", "https://hugg...
Source context: 7 downloads · 0 likes · Pipeline zero-shot-image-classification · Library sentence-transformers · Repo alphaedge-ai/siglip2-giant-opt-patch16-384-kat-16384
