Git Base Vqav2
GIT (short for GenerativeImage2Text) model, base-sized version, fine-tuned on VQAv2. It was introduced in the paper GIT: A Generative Image-to-text Transformer for Vision and Language by Wang et al. and first...
Source du modèle
- Type
- Text model
- Taille du fichier
- 676 MB
- Version
- vmodel
- Mis à jour
- 18 sept. 2026
- Téléchargements
- 661
- Source
- Hugging Face
Description de la source
GIT (GenerativeImage2Text), base-sized, fine-tuned on VQAv2
GIT (short for GenerativeImage2Text) model, base-sized version, fine-tuned on VQAv2. It was introduced in the paper GIT: A Generative Image-to-text Transformer for Vision and Language by Wang et al. and first released in this repository.
Disclaimer: The team releasing GIT did not write a model card for this model so this model card has been written by the Hugging Face team.
Model description
GIT is a Transformer decoder conditioned on both CLIP image tokens and text tokens. The model is trained using "teacher forcing" on a lot of (image, text) pairs.
The goal for the model is simply to predict the next text token, giving the image tokens and previous text tokens.
The model has full access to (i.e. a bidirectional attention mask is used for) the image patch tokens, but only has access to the previous text tokens (i.e. a causal attention mask is used for the text tokens) when predicting the next text token.
GIT architecture
This allows the model to be used for tasks like:
- image and video captioning
- visual question answering (VQA) on images and videos
- even image classification (by simply conditioning the model on the image and asking it to generate a class for it in text).
Intended uses & limitations
You can use the raw model for visual question answering (VQA). See the model hub to look for fine-tuned versions on a task that interests you.
How to use
For code examples, we refer to the documentation.
Training data
From the paper:
We collect 0.8B image-text pairs for pre-training, which include COCO (Lin et al., 2014), Conceptual Captions (CC3M) (Sharma et al., 2018), SBU (Ordonez et al., 2011), Visual Genome (VG) (Krishna et al., 2016), Conceptual Captions (CC12M) (Changpinyo et al., 2021), ALT200M (Hu et al., 2021a), and an extra 0.6B data following a similar collection procedure in Hu et al. (2021a).
=> however this is for the model referred to as "GIT" in the paper, which is not open-sourced.
This checkpoint is "GIT-base", which is a smaller variant of GIT trained on 10 million image-text pairs.
Next, the model was fine-tuned on VQAv2.
See table 11 in the paper for more details.
Preprocessing
We refer to the original repo regarding details for preprocessing during training.
During validation, one resizes the shorter edge of each image, after which center cropping is performed to a fixed-size resolution. Next, frames are normalized across the RGB channels with the ImageNet mean and standard deviation.
Evaluation results
For evaluation results, we refer readers to the paper.
Sources
1 source
Sources
1 sourceVérifié 4 sept.
Artefacts du modèle
1 artefact
Artefacts du modèle
1 artefactExtraits de sources
2 extraits
Extraits de sources
2 extraits--- language: en license: mit tags: - vision model_name: microsoft/git-base-vqav2 inference: false pipeline_tag: visual-question-answering --- # GIT (GenerativeImage2Text), base-sized, fine-tuned on VQAv2 GIT (short for GenerativeImage2Text) model, base-sized version, fine-tuned on VQAv2. It was introduced in the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by Wang et al. and first released in [this repository](https://github.com/microsoft/GenerativeImage2Text). Disclaimer: The team releasing GIT did not write a model card for this model so this model card has been written by the Hugging Face team. ## Model description GIT is a Transformer decoder conditioned on both CLIP image tokens and text tokens. The model is trained using "teacher forcing" on a lot of (image, text) pairs. The goal for the model is simply to predict the next text token, giving the image tokens and previous text tokens. The model has full access to (i.e. a bidirectional attention mask is used for) the image patch tokens, but only has access to the previous text tokens (i.e. a causal attention mask is used for the text tokens) when predicting the next text token. 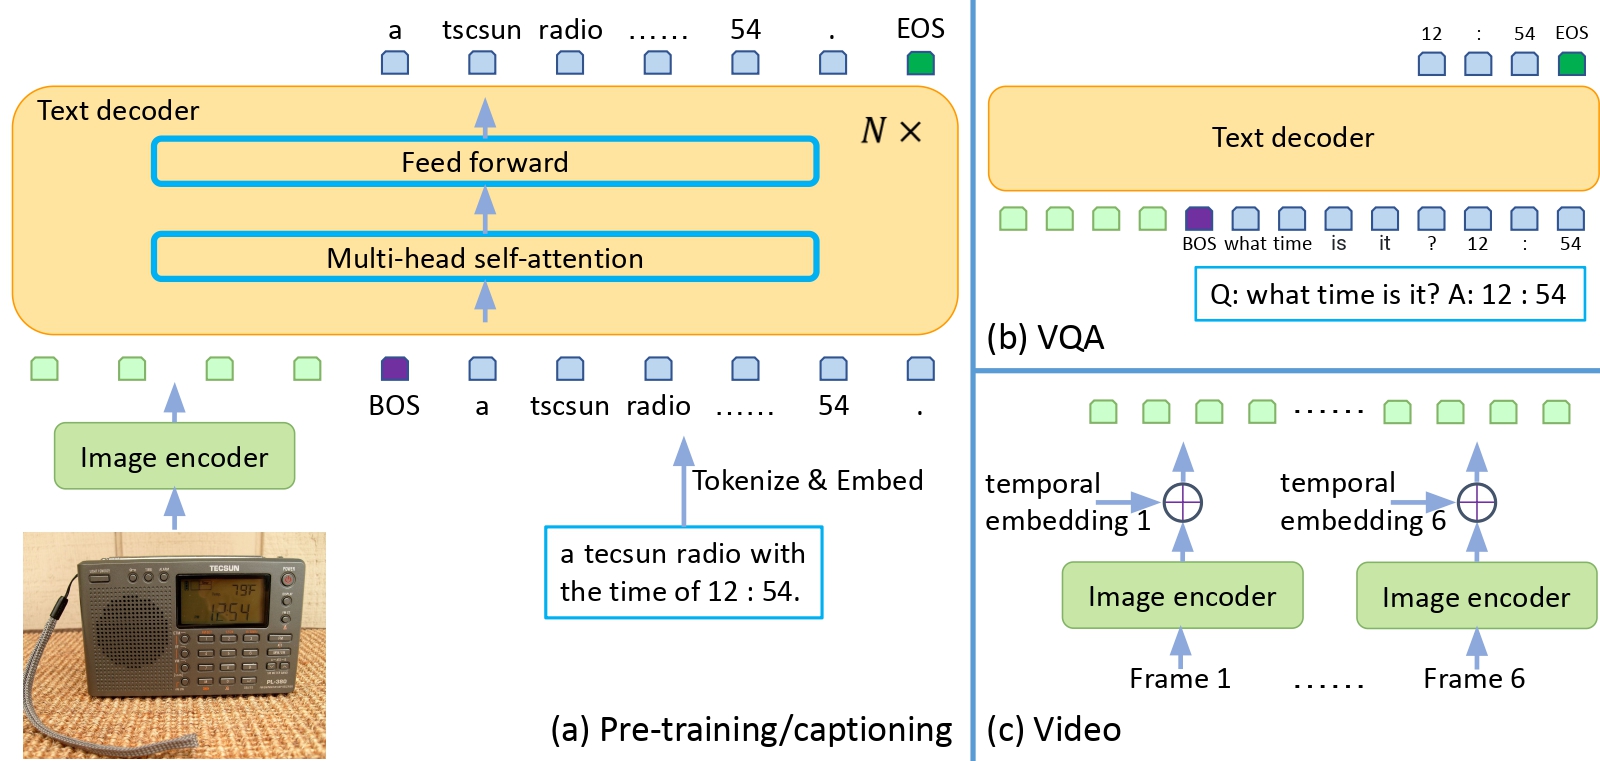 This allows the model to be used for tasks like: - image and video captioning - visual question answering (VQA) on images and videos - even image classification (by simply conditioning the model on the image and asking it to generate a class for it in text). ## Intended uses & limitations You can use the raw model for visual question answering (VQA). See the [model hub](https://huggingface.co/models?search=microsoft/git) to look for fine-tuned versions on a task that interests you. ### How to use For code examples, we refer to the [documentation](https://huggingface.co/docs/transformers/main/model_doc/git#transformers.GitForCausalLM.forward.example-2). ## Training data From the paper: > We collect 0.8B image-text pairs for pre-training, which include COCO (Lin et al., 2014), Conceptual Captions (CC3M) (Sharma et al., 2018), SBU (Ordonez et al., 2011), Visual Genome (VG) (Krishna et al., 2016), Conceptual Captions (CC12M) (Changpinyo et al., 2021), ALT200M (Hu et al., 2021a), and an extra 0.6B data followin...
Source context: 661 downloads · 21 likes · Pipeline visual-question-answering · Library transformers · Repo microsoft/git-base-vqav2