Gemma 4 31B It DASHQ INT2 G32
> DASH-Q — Diagonal-Aware Shrinkage for Robust PTQ. > INT2 · group size 32 · 14.9555 GB (from 62.5463 GB — 4.2x smaller)
Fuente del modelo
- Tipo
- Text model
- Tamaño del archivo
- Aún no registrado
- Modelo base
- google/gemma-4-31B-it
- Versión
- vRevision 6db6c86
- Actualizado
- 8 oct 2026
- Publicador
- @jkim96
- Descargas
- 15
- Parámetros
- 31B
- Fuente
- Hugging Face
Descripción de la fuente
DASH-Q
gemma-4-31B-it-DASHQ-INT2-g32
DASH-Q — Diagonal-Aware Shrinkage for Robust PTQ.
INT2· group size 32 · 14.9555 GB (from 62.5463 GB — 4.2x smaller)
DASH-Q checkpoints load with the lightweight DASH-Q runtime — linear layers are packed PackedQuantizedLinear modules, not plain Transformers weights.
Install
pip install git+https://github.com/JaeminK/dashq.git
Load
from dashq import load_quantized

model, tokenizer = load_quantized("jkim96/gemma-4-31B-it-DASHQ-INT2-g32", device_map="auto")
Quantization
| Field | Value |
|---|---|
| Base model | google/gemma-4-31B-it |
| Precision | INT2, group size 32 |
| Scale / zero dtype | float16 |
| Calibration | c4, 512 samples x 2048 |
| Size | 14.9555 GB · original 62.5463 GB · 4.2x compression |
Benchmarks
Full zero-shot / few-shot results for every DASH-Q checkpoint: github.com/JaeminK/dashq#benchmarks
Fuentes
1 fuente
Fuentes
1 fuenteVerificado 6 ago
Extractos de fuentes
3 extractos
Extractos de fuentes
3 extractos--- license: apache-2.0 base_model: google/gemma-4-31B-it base_model_relation: quantized library_name: transformers tags: - dashq - quantized - post-training-quantization - int2 --- 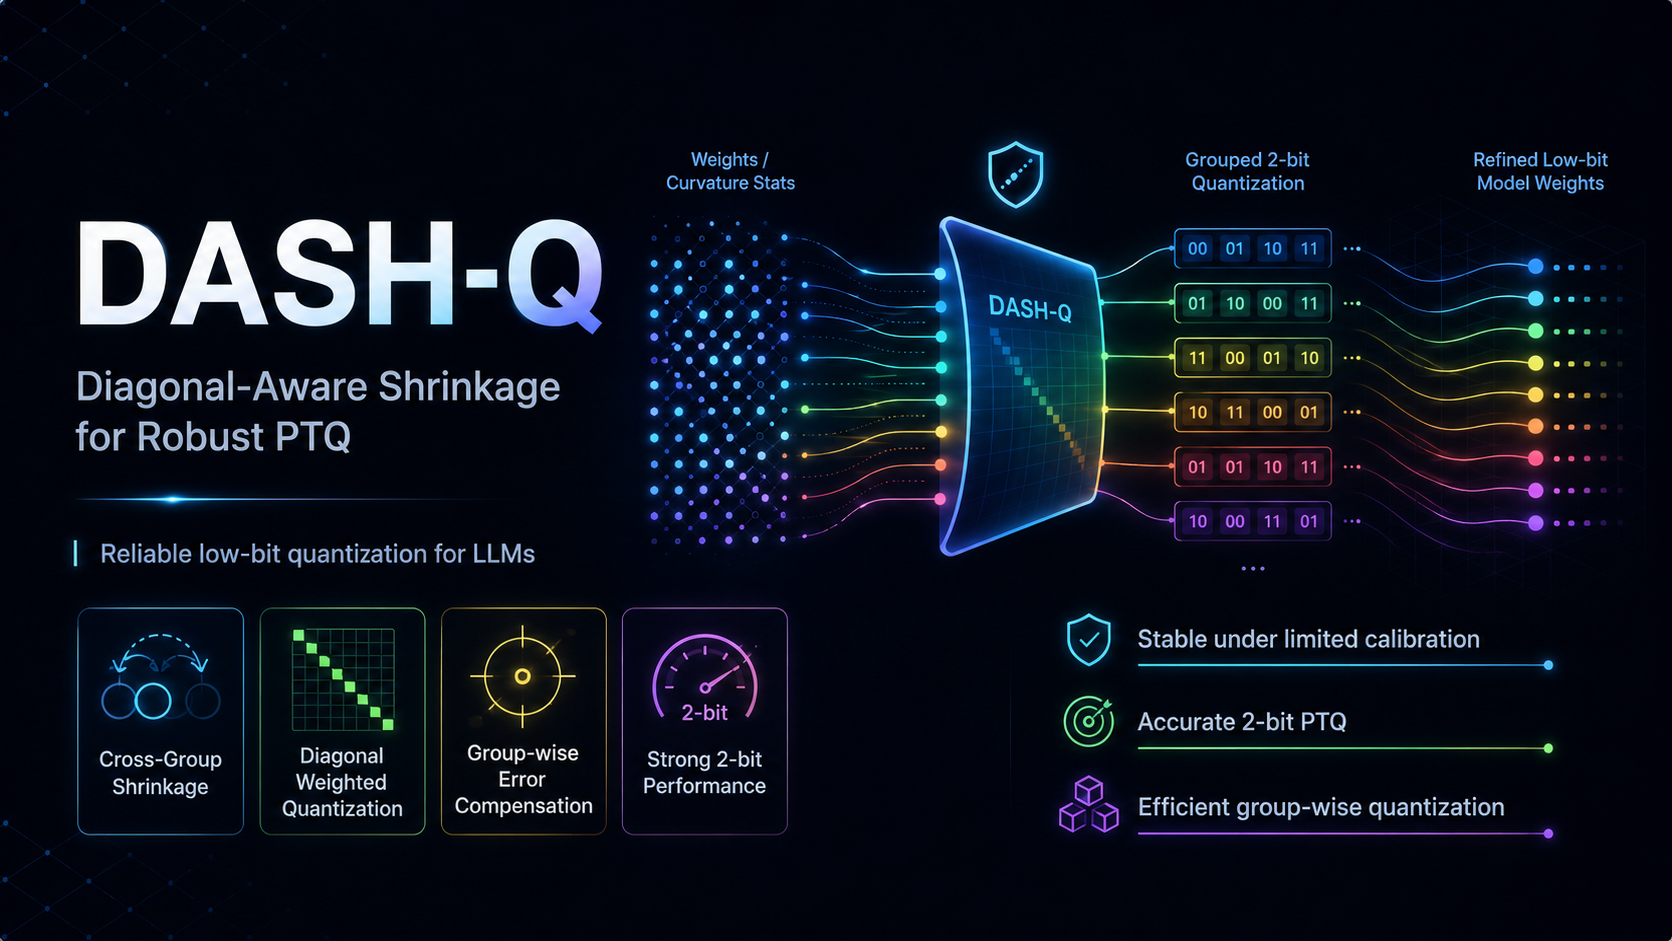 # gemma-4-31B-it-DASHQ-INT2-g32 > **DASH-Q** — Diagonal-Aware Shrinkage for Robust PTQ. > `INT2` · group size 32 · **14.9555 GB** (from 62.5463 GB — **4.2x smaller**) DASH-Q checkpoints load with the lightweight DASH-Q runtime — linear layers are packed `PackedQuantizedLinear` modules, not plain Transformers weights. ## Install ```bash pip install git+https://github.com/JaeminK/dashq.git ``` ## Load ```python from dashq import load_quantized model, tokenizer = load_quantized("jkim96/gemma-4-31B-it-DASHQ-INT2-g32", device_map="auto") ``` ## Quantization | Field | Value | | --- | --- | | Base model | `google/gemma-4-31B-it` | | Precision | INT2, group size 32 | | Scale / zero dtype | float16 | | Calibration | c4, 512 samples x 2048 | | Size | 14.9555 GB · original 62.5463 GB · 4.2x compression | ## Benchmarks Full zero-shot / few-shot results for every DASH-Q checkpoint: **[github.com/JaeminK/dashq#benchmarks](https://github.com/JaeminK/dashq#benchmarks)**
Source context: 15 downloads · 0 likes · Pipeline image-text-to-text · Library transformers · Repo jkim96/gemma-4-31B-it-DASHQ-INT2-g32
Source context: 56 downloads · 0 likes · Pipeline image-text-to-text · Library transformers · Repo jkim96/gemma-4-31B-it-DASHQ-INT2-g32
