Qwen3 30b Nomem 6skill 0617 Iter319
We introduce the updated version of the Qwen3-30B-A3B non-thinking mode, named Qwen3-30B-A3B-Instruct-2507, featuring the following key enhancements:
Modellquelle
- Art
- Text model
- Dateigröße
- Noch nicht aufgezeichnet
- Version
- vRevision 822788d
- Aktualisiert
- 27. Sept. 2026
- Verleger
- @spare-rl
- Downloads
- 18
- Parameter
- 30B
- Aufgaben
- Textgenerierung
- Quelle
- Hugging Face
Quellenauszug
We introduce the updated version of the Qwen3-30B-A3B non-thinking mode, named Qwen3-30B-A3B-Instruct-2507, featuring the following key enhancements:
Quellen
1 Quelle
Quellen
1 QuelleVerifiziert 27. Sept.
Quellenauszüge
3 Auszüge
Quellenauszüge
3 Auszüge--- library_name: transformers license: apache-2.0 license_link: https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507/blob/main/LICENSE pipeline_tag: text-generation --- # Qwen3-30B-A3B-Instruct-2507 <a href="https://chat.qwen.ai/?model=Qwen3-30B-A3B-2507" target="_blank" style="margin: 2px;"> <img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/> </a> ## Highlights We introduce the updated version of the **Qwen3-30B-A3B non-thinking mode**, named **Qwen3-30B-A3B-Instruct-2507**, featuring the following key enhancements: - **Significant improvements** in general capabilities, including **instruction following, logical reasoning, text comprehension, mathematics, science, coding and tool usage**. - **Substantial gains** in long-tail knowledge coverage across **multiple languages**. - **Markedly better alignment** with user preferences in **subjective and open-ended tasks**, enabling more helpful responses and higher-quality text generation. - **Enhanced capabilities** in **256K long-context understanding**. 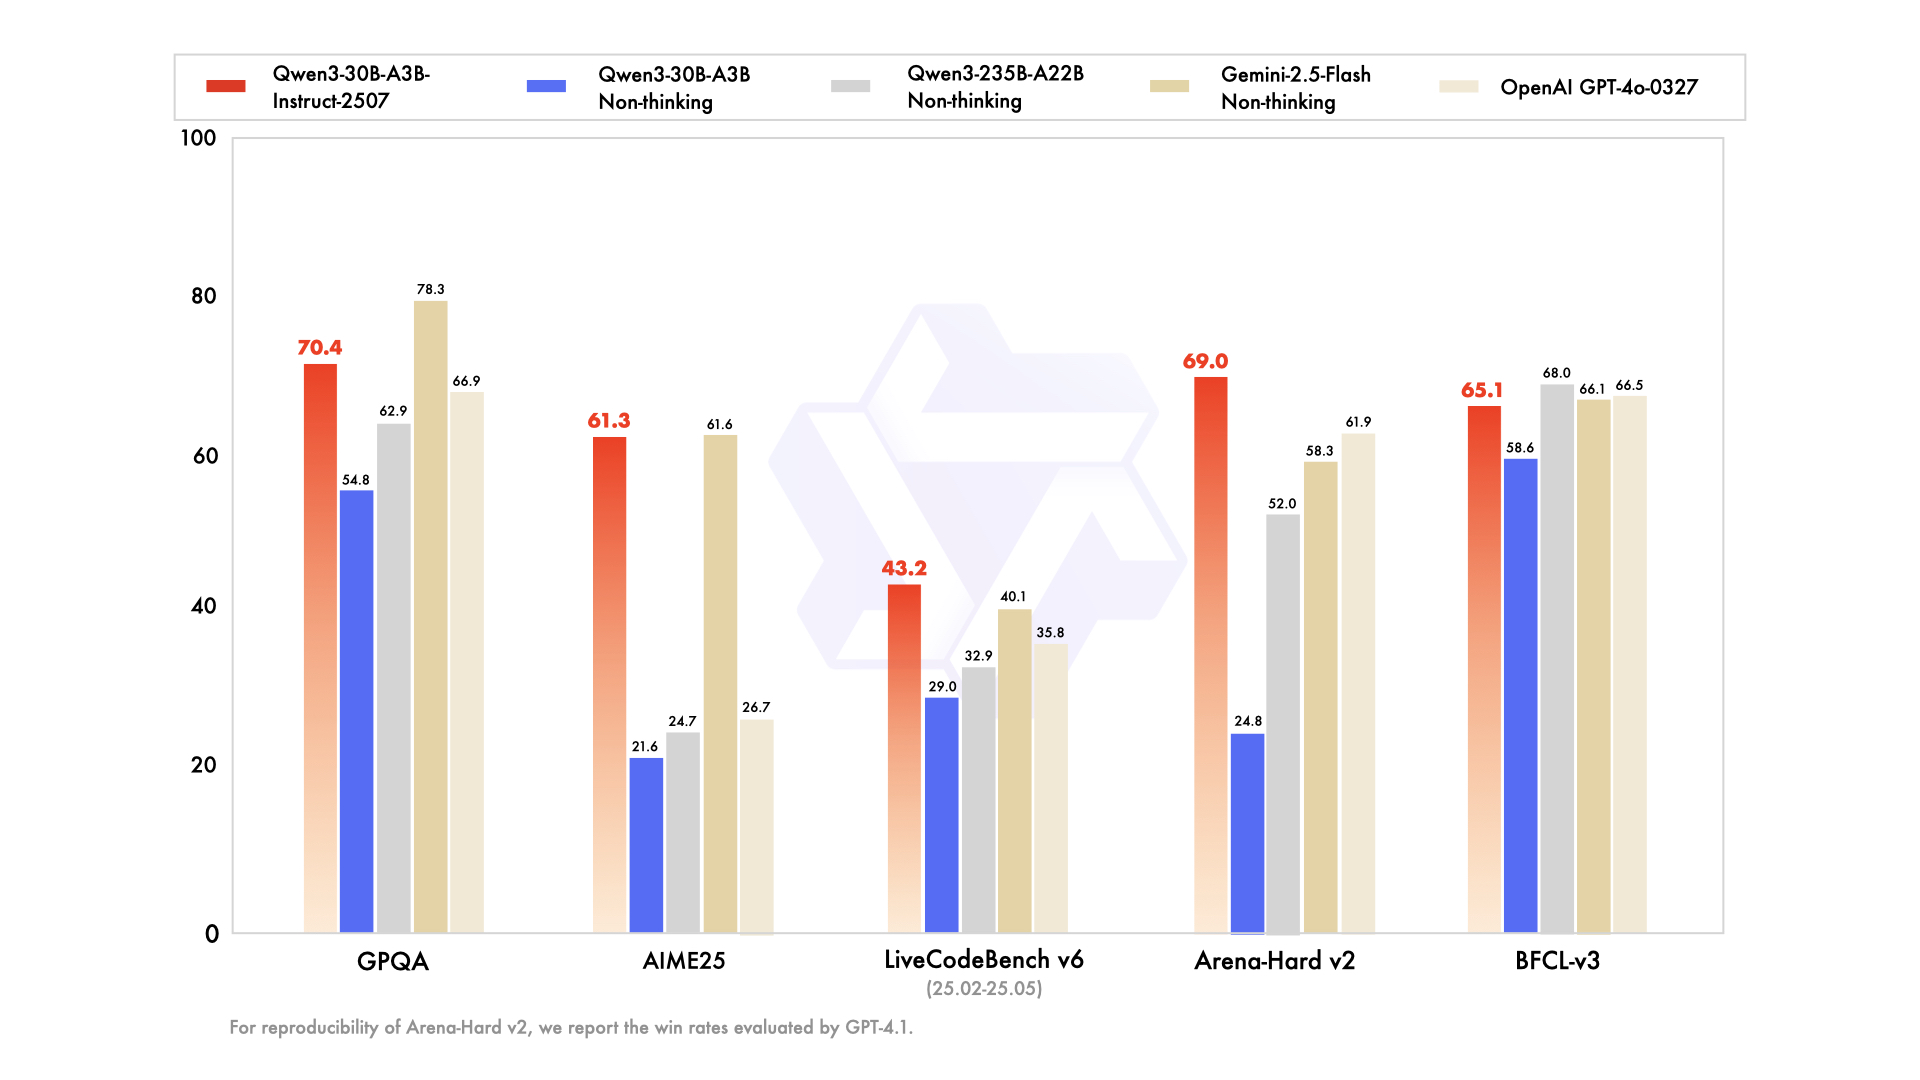 ## Model Overview **Qwen3-30B-A3B-Instruct-2507** has the following features: - Type: Causal Language Models - Training Stage: Pretraining & Post-training - Number of Parameters: 30.5B in total and 3.3B activated - Number of Paramaters (Non-Embedding): 29.9B - Number of Layers: 48 - Number of Attention Heads (GQA): 32 for Q and 4 for KV - Number of Experts: 128 - Number of Activated Experts: 8 - Context Length: **262,144 natively**. **NOTE: This model supports only non-thinking mode and does not generate ``<think></think>`` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.** For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3/), [GitHub](https://github.com/QwenLM/Qwen3), and [Documentation](https://qwen.readthedocs.io/en/latest/). ## Performance | | Deepseek-V3-0324 | GPT-4o-0327 | Gemini-2.5-Flash Non-Thinking | Qwen3-235B-A22B Non-Thinking | Qwen3-30B-A3B Non-Thinking | Qwen3-30B-A3B-Instruct-2507 | |--- | --- | --- | --- | --- | --- | --- | | **Knowledge** | | | | | | | | MMLU-Pro | **...
Source context: 18 downloads · 0 likes · Pipeline text-generation · Library transformers · Repo msr-spare/qwen3-30b-nomem-6skill-0617-iter319
Source context: 17 downloads · 0 likes · Pipeline text-generation · Library transformers · Repo spare-rl/qwen3-30b-nomem-6skill-0617-iter319
