Mvrag
| Project Page | Paper | GitHub | Weights | Benchmark (OOD-Eval) |
Modellquelle
- Art
- Other
- Dateigröße
- 160 MB–3,33 GB
- Basismodell
- ashawkey/mvdream-sd2.1-diffusers
- Version
- vRevision fcf457a
- Aktualisiert
- 10. Okt. 2026
- Downloads
- 12
- Quelle
- Hugging Face
Quellenbeschreibung
MV-RAG: Retrieval Augmented Multiview Diffusion
| Project Page | Paper | GitHub | Weights | Benchmark (OOD-Eval) |
teaser
Abstract
Text-to-3D generation approaches have advanced significantly by leveraging pretrained 2D diffusion priors, producing high-quality and 3D-consistent outputs. However, they often fail to produce out-of-domain (OOD) or rare concepts, yielding inconsistent or inaccurate results. To this end, we propose MV-RAG, a novel text-to-3D pipeline that first retrieves relevant 2D images from a large in-the-wild 2D database and then conditions a multiview diffusion model on these images to synthesize consistent and accurate multiview outputs. Training such a retrieval-conditioned model is achieved via a novel hybrid strategy bridging structured multiview data and diverse 2D image collections. This involves training on multiview data using augmented conditioning views that simulate retrieval variance for view-specific reconstruction, alongside training on sets of retrieved real-world 2D images using a distinctive held-out view prediction objective: the model predicts the held-out view from the other views to infer 3D consistency from 2D data. To facilitate a rigorous OOD evaluation, we introduce a new collection of challenging OOD prompts. Experiments against state-of-the-art text-to-3D, image-to-3D, and personalization baselines show that our approach significantly improves 3D consistency, photorealism, and text adherence for OOD/rare concepts, while maintaining competitive performance on standard benchmarks.
Overview
MV-RAG is a text-to-3D generation method that retrieves 2D reference images to guide a multiview diffusion model. By conditioning on both text and multiple real-world 2D images, MV-RAG improves realism and consistency for rare/out-of-distribution or newly emerging objects.
Installation
We recommend creating a fresh conda environment to run MV-RAG:
# Clone the repository
git clone https://github.com/yosefdayani/MV-RAG.git
cd MV-RAG

# Create new environment
conda create -n mvrag python=3.9 -y
conda activate mvrag

# Install PyTorch (adjust CUDA version as needed)
# Example: CUDA 12.4, PyTorch 2.5.1
conda install pytorch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 pytorch-cuda=12.4 -c pytorch -c nvidia

# Install other dependencies
pip install -r requirements.txt
Weights
MV-RAG weights are available on Hugging Face.
# Make sure git-lfs is installed (https://git-lfs.com)
git lfs install

git clone https://huggingface.co/yosepyossi/mvrag
Then the model weights should appear as MV-RAG/mvrag/...
Usage Example
You could prompt the model on your retrieved local images by:
python main.py \
--prompt "Cadillac 341 automobile car" \
--retriever simple \
--folder_path "assets/Cadillac 341 automobile car" \
--seed 0 \
--k 4 \
--azimuth_start 45  # or 0 for front view
To see all command options run
python main.py --help
Acknowledgement
This repository is based on MVDream and adapted from MVDream Diffusers. We would like to thank the authors of these works for publicly releasing their code.
Citation
@misc{dayani2025mvragretrievalaugmentedmultiview,
      title={MV-RAG: Retrieval Augmented Multiview Diffusion},
      author={Yosef Dayani and Omer Benishu and Sagie Benaim},
      year={2025},
      eprint={2508.16577},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2508.16577},
}
Quellen
1 Quelle
Quellen
1 QuelleVerifiziert 10. Okt.
Download files
Modellartefakte
5 Artefakte
Modellartefakte
5 Artefakteimage_encoder/model.safetensors
safetensors · 2,35 GB · SHA-256 8eb46f477ef5…bb84 · Hugging Face
Download fileresampler/model.safetensors
safetensors · 185 MB · SHA-256 089e78f43f1f…1c39 · Hugging Face
Download filetext_encoder/model.safetensors
safetensors · 649 MB · SHA-256 bc1827c46545…e13f · Hugging Face
Download fileunet/diffusion_pytorch_model.safetensors
safetensors · 3,33 GB · SHA-256 db51832f1123…4ff0 · Hugging Face
Download filevae/diffusion_pytorch_model.safetensors
safetensors · 160 MB · SHA-256 3e4c08995484…af9a · Hugging Face
Download fileQuellenauszüge
3 Auszüge
Quellenauszüge
3 Auszüge--- base_model: - ashawkey/mvdream-sd2.1-diffusers datasets: - yosepyossi/OOD-Eval license: cc-by-4.0 pipeline_tag: text-to-3d tags: - multiview - 3D - RAG - retrieval - diffusion library_name: diffusers --- # MV-RAG: Retrieval Augmented Multiview Diffusion | [Project Page](https://yosefdayani.github.io/MV-RAG/) | [Paper](https://huggingface.co/papers/2508.16577) | [GitHub](https://github.com/yosefdayani/MV-RAG) | [Weights](https://huggingface.co/yosepyossi/mvrag) | [Benchmark (OOD-Eval)](https://huggingface.co/datasets/yosepyossi/OOD-Eval) | 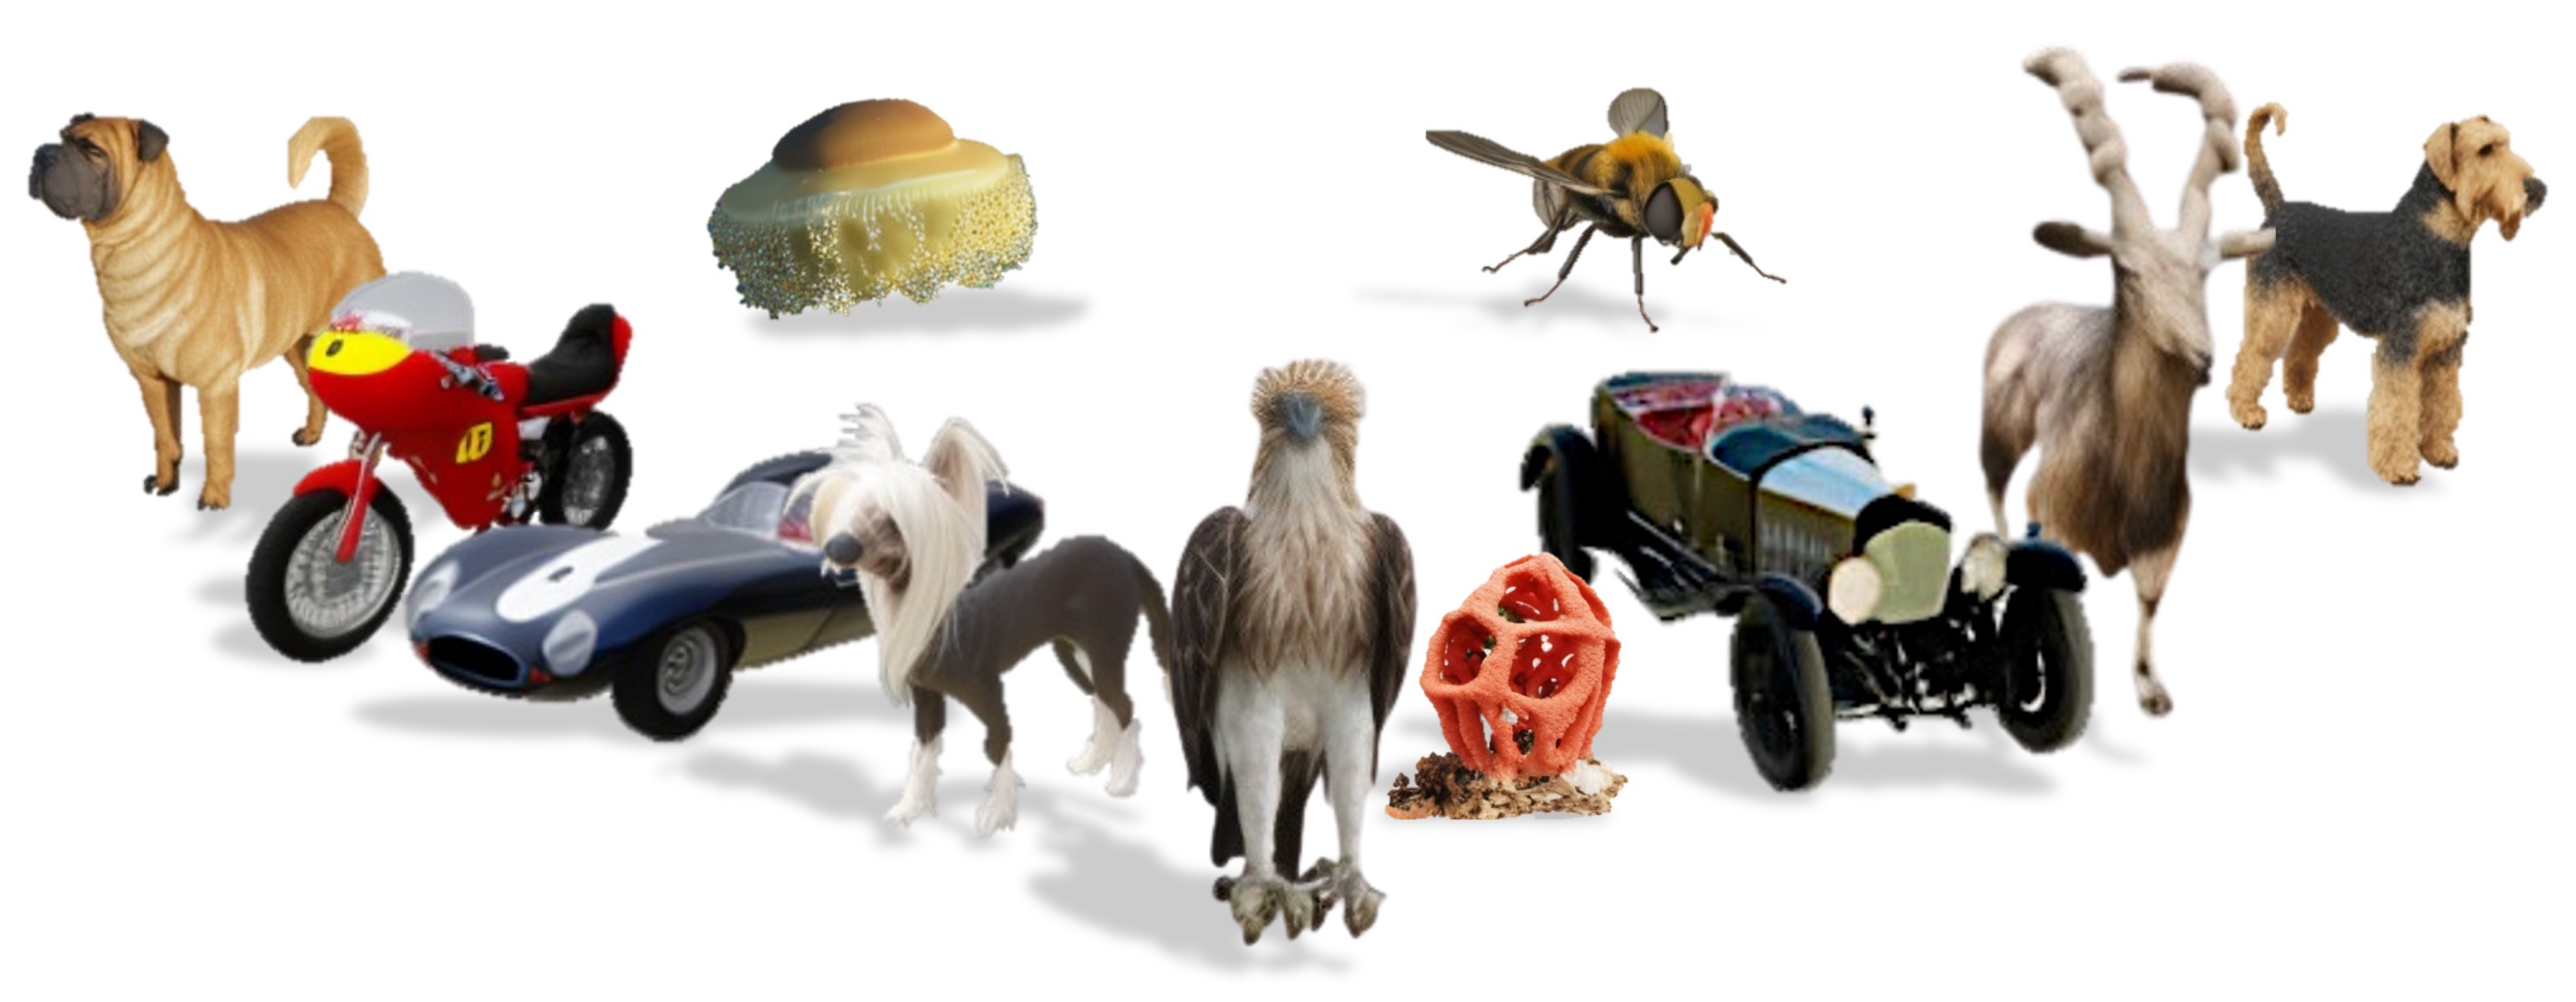 ## Abstract Text-to-3D generation approaches have advanced significantly by leveraging pretrained 2D diffusion priors, producing high-quality and 3D-consistent outputs. However, they often fail to produce out-of-domain (OOD) or rare concepts, yielding inconsistent or inaccurate results. To this end, we propose MV-RAG, a novel text-to-3D pipeline that first retrieves relevant 2D images from a large in-the-wild 2D database and then conditions a multiview diffusion model on these images to synthesize consistent and accurate multiview outputs. Training such a retrieval-conditioned model is achieved via a novel hybrid strategy bridging structured multiview data and diverse 2D image collections. This involves training on multiview data using augmented conditioning views that simulate retrieval variance for view-specific reconstruction, alongside training on sets of retrieved real-world 2D images using a distinctive held-out view prediction objective: the model predicts the held-out view from the other views to infer 3D consistency from 2D data. To facilitate a rigorous OOD evaluation, we introduce a new collection of challenging OOD prompts. Experiments against state-of-the-art text-to-3D, image-to-3D, and personalization baselines show that our approach significantly improves 3D consistency, photorealism, and text adherence for OOD/rare concepts, while maintaining competitive performance on standard benchmarks. ## Overview MV-RAG is a text-to-3D generation method that retrieves 2D reference images to guide a multiview diffusion model. By conditioning on both text and multiple real-world 2D images, MV-RAG improves realism and consistency for rare/out-of-distribution or newly emerging objects. ## Installation We recommend creating a fresh conda...
Source context: 12 downloads · 1 likes · Pipeline text-to-3d · Library diffusers · Repo yosepyossi/mvrag
Source context: 27 downloads · 1 likes · Pipeline text-to-3d · Library diffusers · Repo yosepyossi/mvrag
