¿Tienes un flujo de trabajo de ComfyUI? Obtén un Workflow Doc legible en tu navegador.Haz legible un flujo de trabajo.Pruébalo ahora ↗
We introduce the updated version of the Qwen3-4B non-thinking mode, named Qwen3-4B-Instruct-2507, featuring the following key enhancements:
Fuente del modelo
Extracto de la fuente
We introduce the updated version of the Qwen3-4B non-thinking mode, named Qwen3-4B-Instruct-2507, featuring the following key enhancements:
Fuentes
1 fuenteArtefactos del modelo
3 artefactosmodel-00001-of-00003.safetensors
safetensors · 3,69 GB · SHA-256 75311d91bb08…8ed6
model-00002-of-00003.safetensors
safetensors · 3,71 GB · SHA-256 0b48adbb1f60…fba1
model-00003-of-00003.safetensors
safetensors · 95,0 MB · SHA-256 7dd39ccca5e4…0d5d
Extractos de fuentes
3 extractos--- library_name: transformers license: apache-2.0 license_link: https://huggingface.co/Qwen/Qwen3-4B-Instruct-2507/blob/main/LICENSE pipeline_tag: text-generation --- # Qwen3-4B-Instruct-2507 <a href="https://chat.qwen.ai" target="_blank" style="margin: 2px;"> <img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/> </a> ## Highlights We introduce the updated version of the **Qwen3-4B non-thinking mode**, named **Qwen3-4B-Instruct-2507**, featuring the following key enhancements: - **Significant improvements** in general capabilities, including **instruction following, logical reasoning, text comprehension, mathematics, science, coding and tool usage**. - **Substantial gains** in long-tail knowledge coverage across **multiple languages**. - **Markedly better alignment** with user preferences in **subjective and open-ended tasks**, enabling more helpful responses and higher-quality text generation. - **Enhanced capabilities** in **256K long-context understanding**. 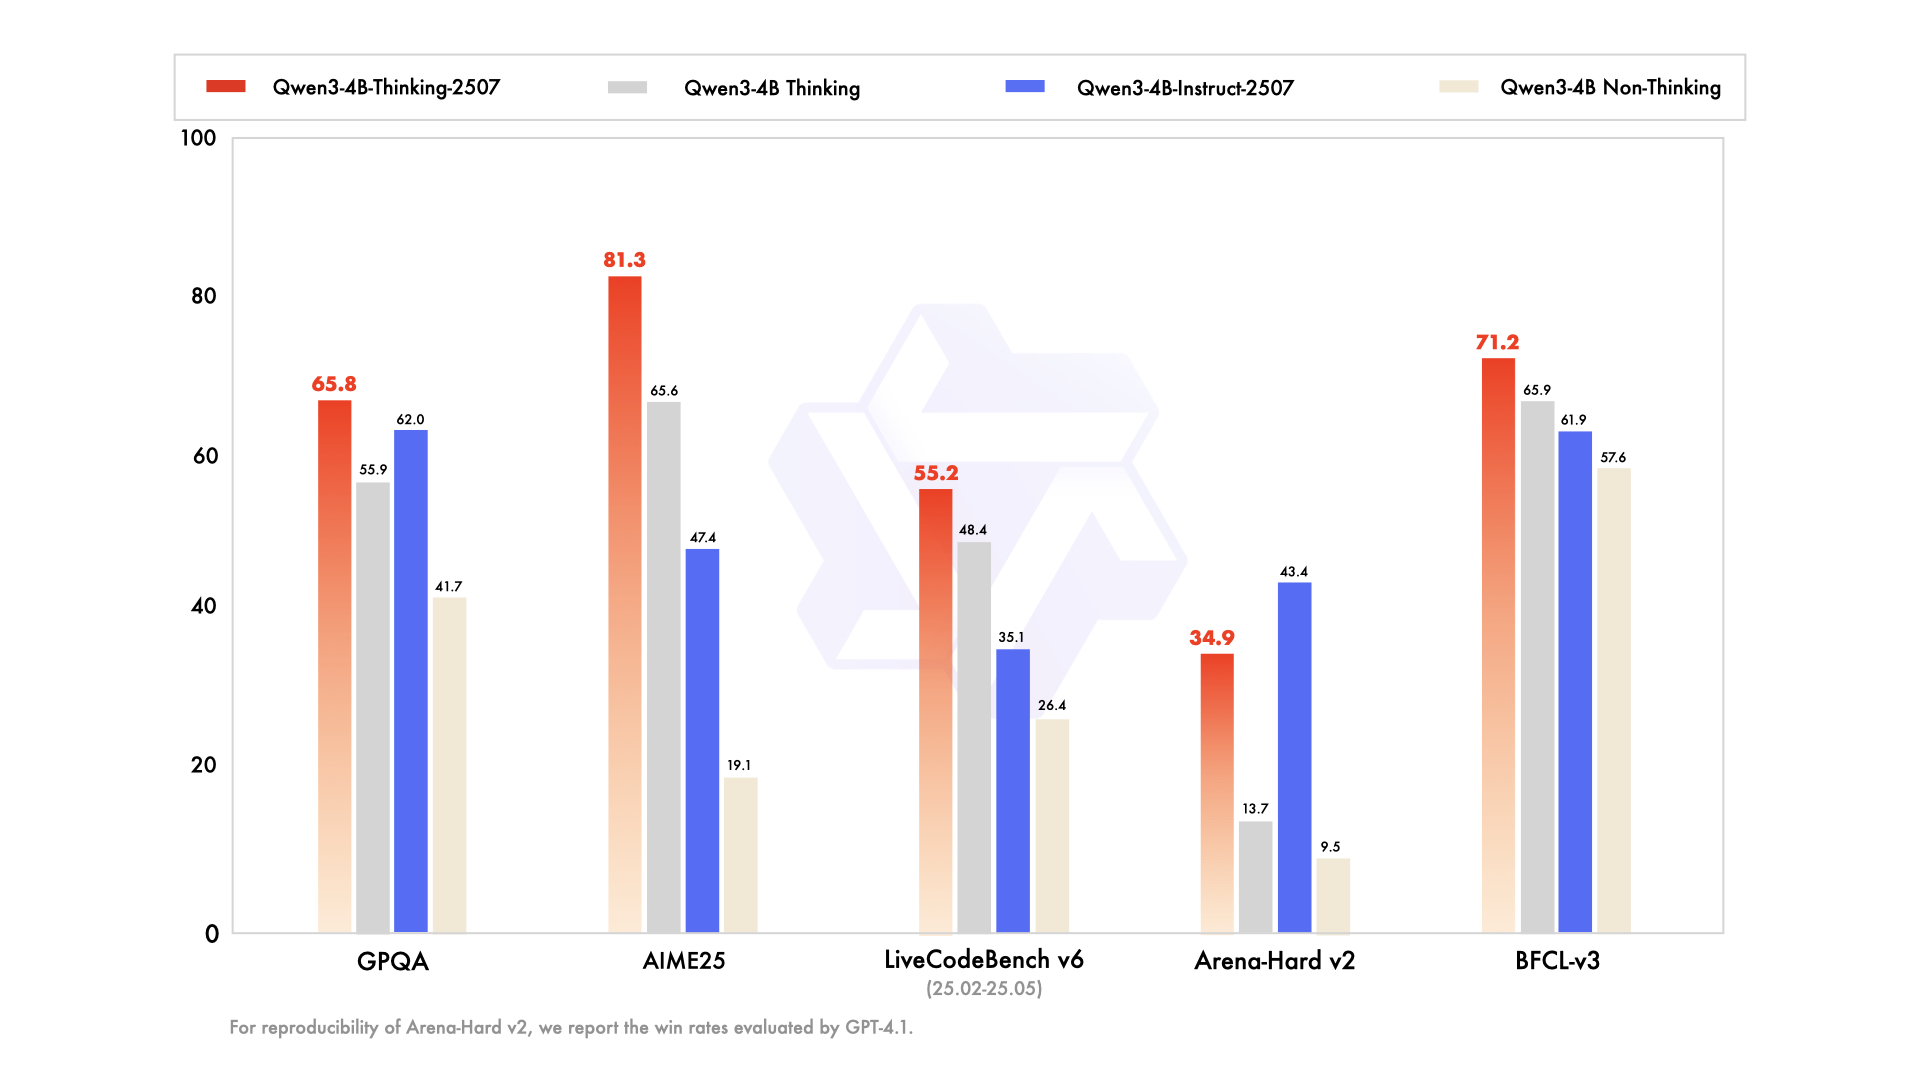 ## Model Overview **Qwen3-4B-Instruct-2507** has the following features: - Type: Causal Language Models - Training Stage: Pretraining & Post-training - Number of Parameters: 4.0B - Number of Paramaters (Non-Embedding): 3.6B - Number of Layers: 36 - Number of Attention Heads (GQA): 32 for Q and 8 for KV - Context Length: **262,144 natively**. **NOTE: This model supports only non-thinking mode and does not generate ``<think></think>`` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.** For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3/), [GitHub](https://github.com/QwenLM/Qwen3), and [Documentation](https://qwen.readthedocs.io/en/latest/). ## Performance | | GPT-4.1-nano-2025-04-14 | Qwen3-30B-A3B Non-Thinking | Qwen3-4B Non-Thinking | Qwen3-4B-Instruct-2507 | |--- | --- | --- | --- | --- | | **Knowledge** | | | | | MMLU-Pro | 62.8 | 69.1 | 58.0 | **69.6** | | MMLU-Redux | 80.2 | 84.1 | 77.3 | **84.2** | | GPQA | 50.3 | 54.8 | 41.7 | **62.0** | | SuperGPQA | 32.2 | 42.2 | 32.0 | **42.8** | | **Reasoning** | | | | | AIME25 | 22.7 | 21.6 | 1...
Source context: 3238838 downloads · 911 likes · Pipeline text-generation · Library transformers · Repo Qwen/Qwen3-4B-Instruct-2507
Source context: 4207873 downloads · 898 likes · Pipeline text-generation · Library transformers · Repo Qwen/Qwen3-4B-Instruct-2507
